NeurIPS 2026
RoMo motion ecosystem
RoMo Hands
A Large Scale Richly Organized Text to Hand Motion Dataset
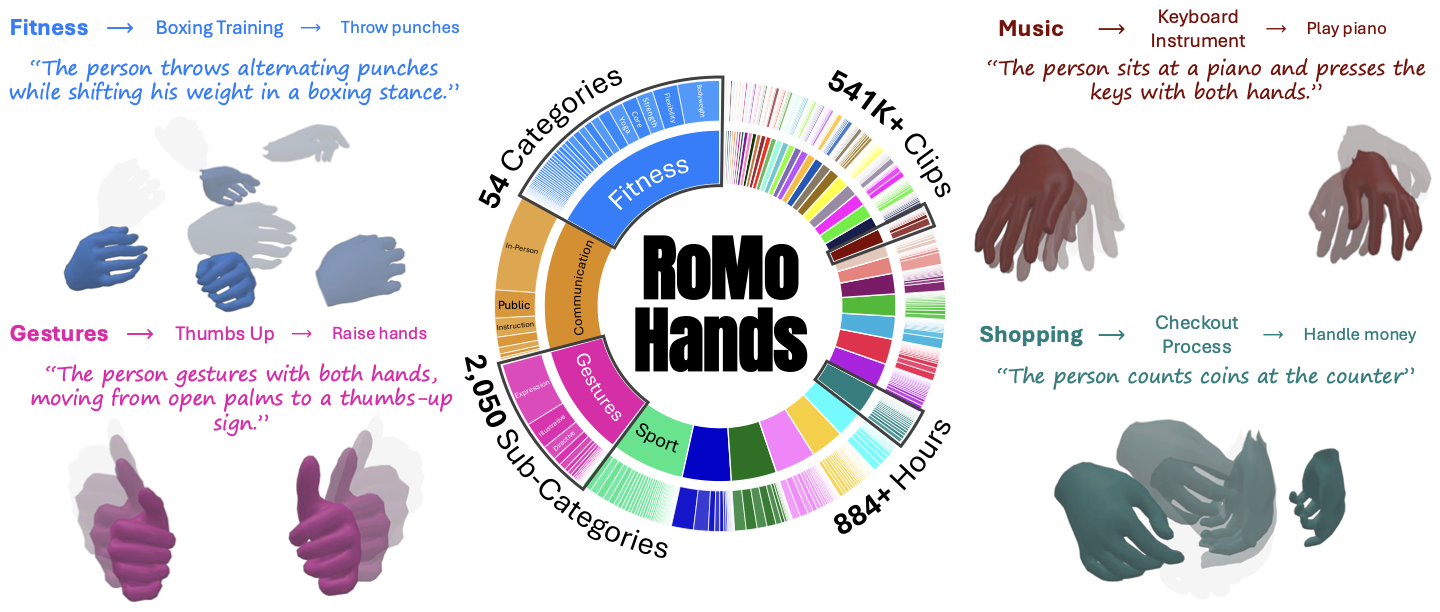
Motion gallery
Hand motion in context
Every card is a real RoMo Hands sequence. The hands are highlighted in pink; drag to orbit, scroll to zoom, and hover to inspect the motion.
Loading hand animations…
Overview
Body-scale data for dexterous hand motion
Text-driven body motion generation has advanced rapidly, but pure-hand synthesis remains bottlenecked by data. Existing datasets often treat hands as rigid end-effectors, lack fine-grained captions, or are too small for modern generative models.
RoMo Hands introduces approximately 542K in-the-wild bimanual sequences spanning 884 hours and 95.5 million frames. Each sequence carries five caption levels, from a compact action tag to a paragraph describing finger articulation, temporal dynamics, palm orientation, and spatial relations.
We also introduce a 393-D bimanual representation and benchmark diffusion, masked-token, and autoregressive generators. The central result is not a single winner: semantic alignment and physical plausibility produce different rankings, showing why hand-motion generation requires both kinds of evaluation.
Explore the work
Go deeper, one layer at a time
Explore the dataset, representation, benchmark, and quality audit without turning the main page into the full supplement.
Dataset
Scale without giving up hand detail
RoMo Hands extends the RoMo collection stack with hand-specific reconstruction, filtering, and language supervision.
Scale
Duration and caption volume
10.6× the duration of CLUTCH. Hover for setting and frame counts; use the scope control to focus on pure-hand datasets.
Language
Caption depth by level
Five supervision levels span a 43× range. Hover for mean word counts and comparator values.
In-the-wild bimanual motion
MANO motion recovered from diverse public video, anchored to temporally consistent body wrists and filtered for visibility.
Dexterity-first curation
Detection-ratio and articulation filters suppress occluded, static, and low-information clips before captioning.
Five levels of language
Captions progress from action tags to detailed descriptions of fingers, wrists, interactions, timing, and inferred intent.
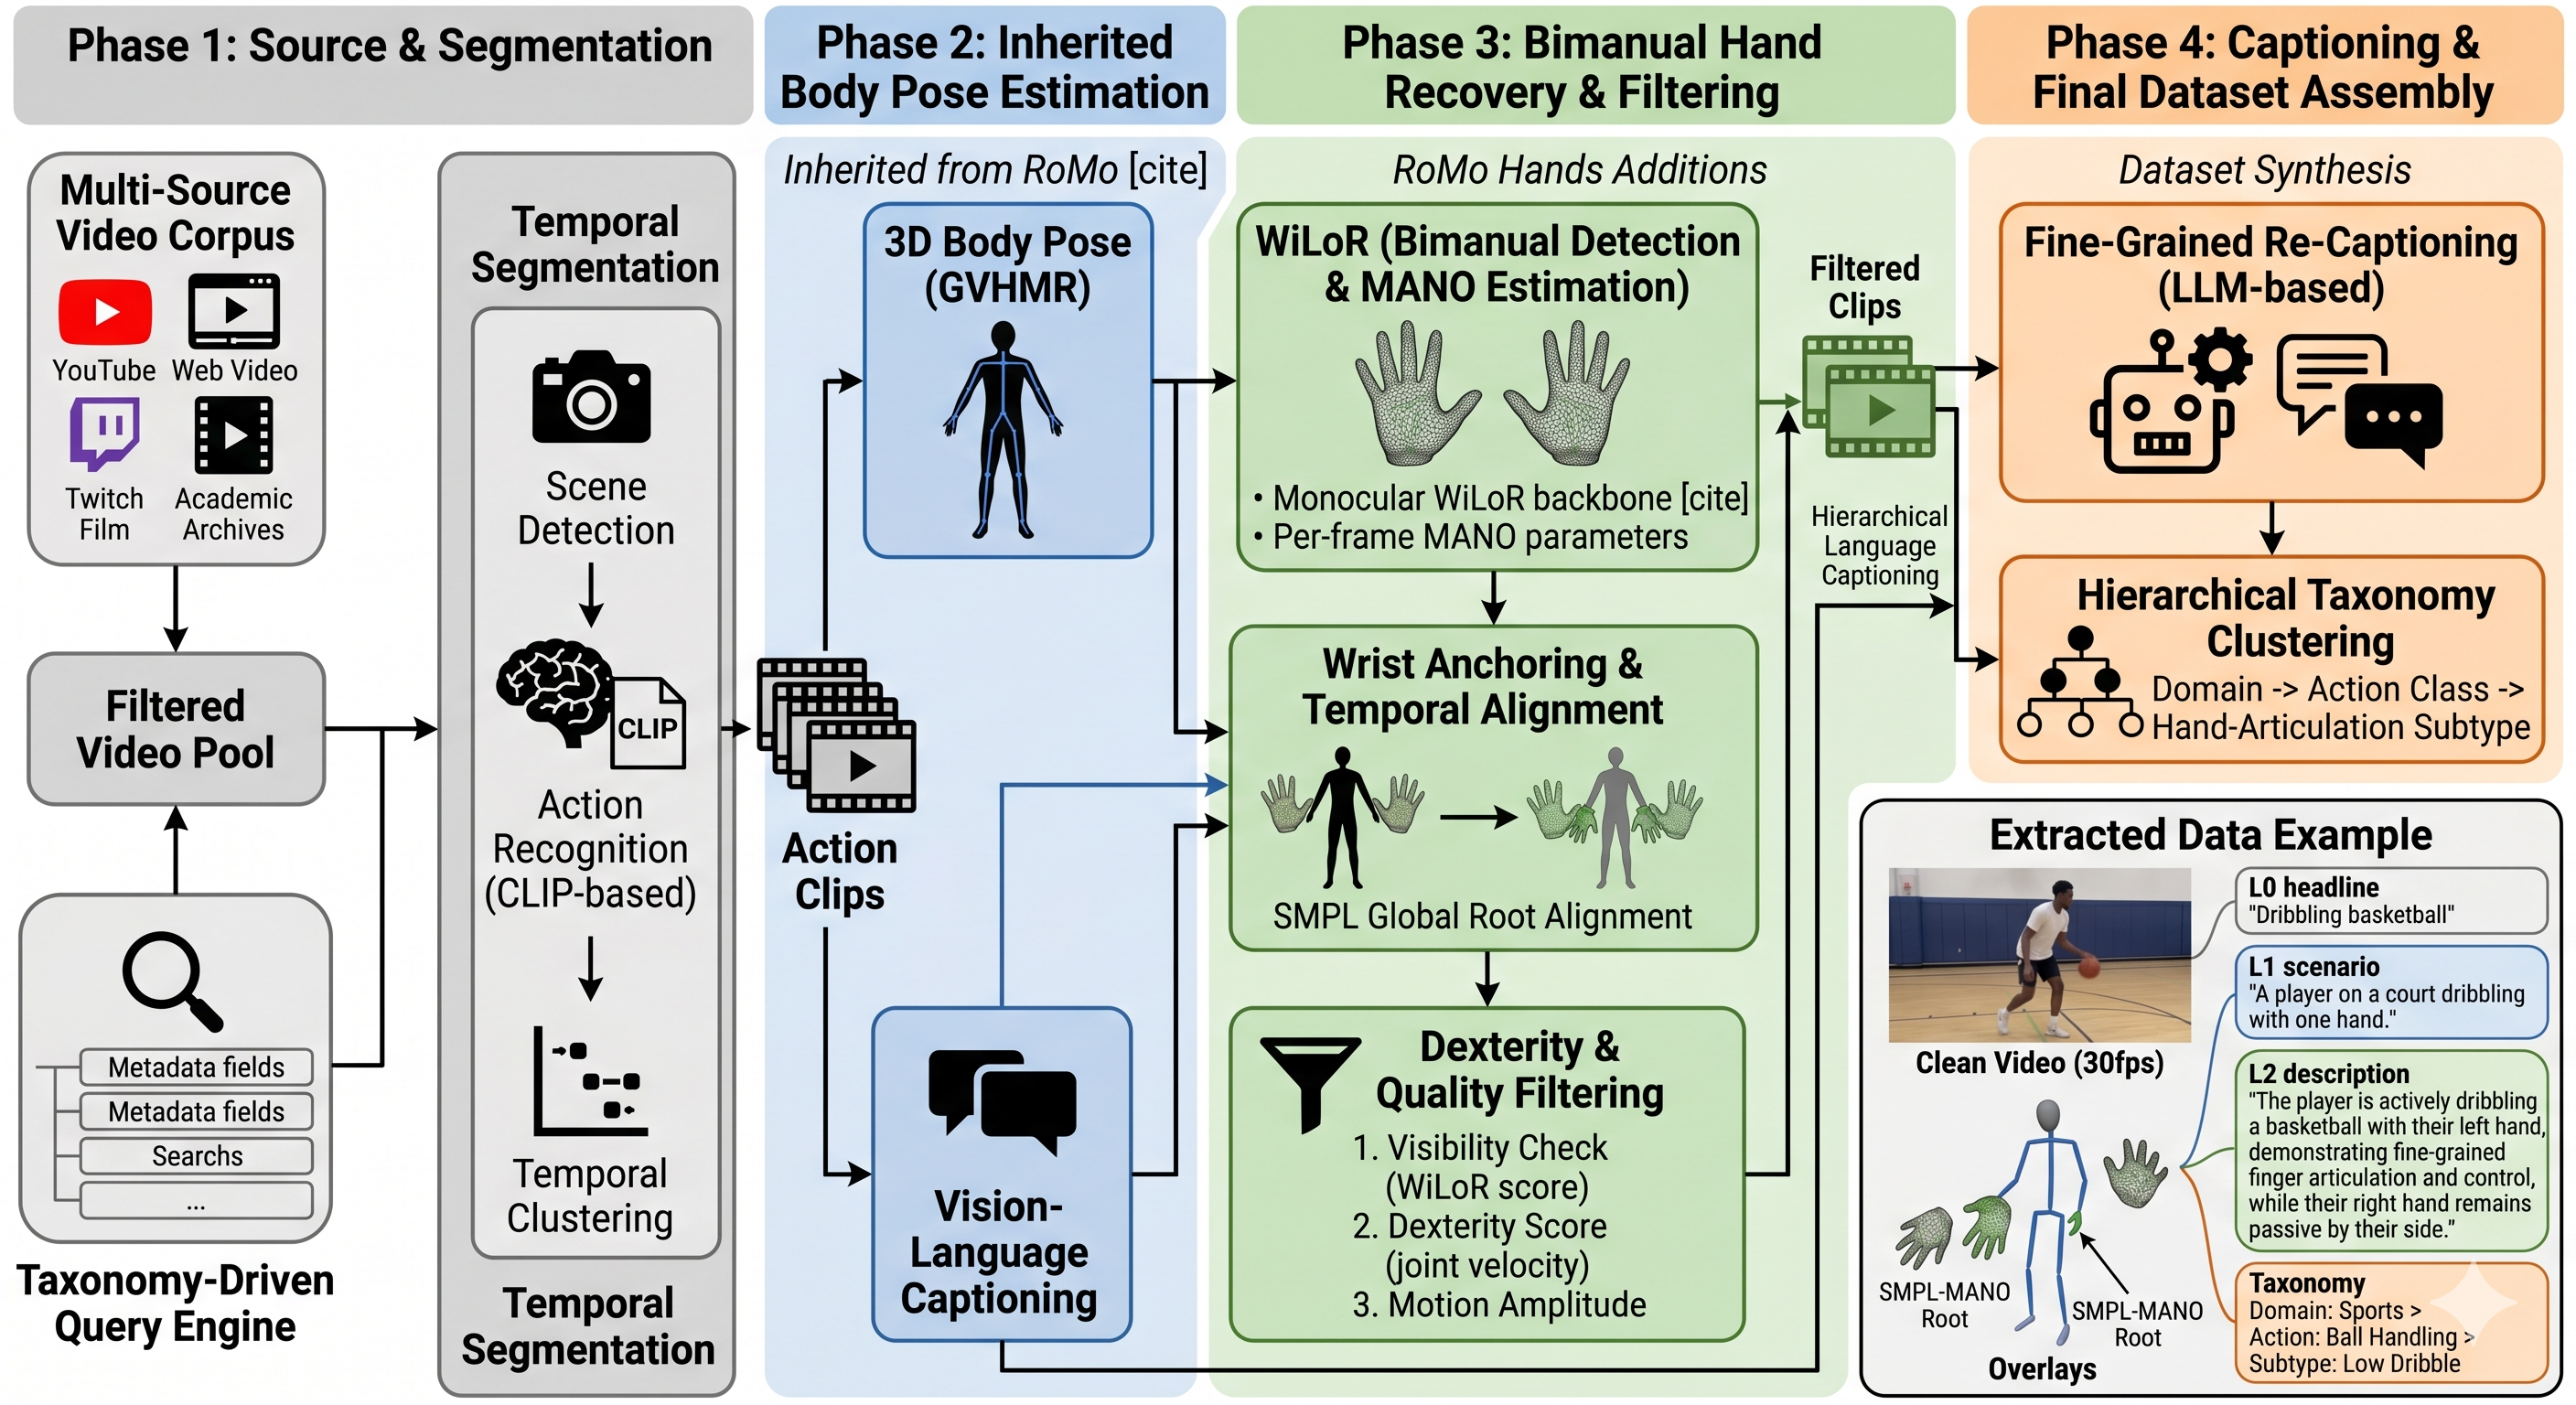
The RoMo Hands curation pipeline.
RoMo's web-video collection and semantic segmentation feed WiLoR hand recovery, wrist anchoring,
dexterity filtering, and five-level captioning.
Representation
A body-style representation built for two hands
Rhand wraps MANO rotations in explicit positions, velocities, and a yaw-only bimanual heading. A synthetic root at the wrist midpoint preserves symmetry without choosing one hand as the anchor.
Symmetric per-frame representation
393 dimensions
Left MANO hand
192-D
48positions
48velocities
966D rotations
16 joints × 12 channels
Right MANO hand
192-D
48positions
48velocities
966D rotations
16 joints × 12 channels
192-D left
+
9-D shared root
+
192-D right
=
393-D
32 MANO joints
Wrist-midpoint root
Inter-wrist heading
Type-aware normalization
Generation-side ablation
Redundant channels help across two generator families
With architecture and training held fixed, the full representation improves R@1 from 39.5% to 54.7% over raw MANO for MoMask and from 64.6% to 66.5% for Kimodo M.
The Kimodo M models were retrained for this ablation and are not directly comparable to the benchmark table.
| Representation | MoMask | Kimodo M |
|---|---|---|
| Rhand-393 | 54.7% | 66.5% |
| MANO-102 | 39.5% | 64.6% |
| CLUTCH-198 | 36.8% | 64.6% |
Benchmark
Semantic alignment is not physical quality
Four generator configurations are evaluated with a shared representation, text encoder, semantic evaluator, and hand-specific physical metrics.
Semantic
Does the motion match the text?
R-Precision, MM-Dist, FID, CLIP alignment, diversity, and multimodality are measured in a frozen text–motion embedding space.
Retrieval leaderMoMaskR@1 54.00%
Physical
Does the hand move plausibly?
Acceleration, local jerk, inter- and self-penetration, and high-frequency power expose failures hidden by retrieval scores.
Cleanest overallKimodo MInter-penetration 1.06%
Taxonomy-stratified evaluation
Model behavior changes by action category
Aggregate scores hide category-specific behavior. Select a category and hover each axis for its raw metric value.
Quality audit
Human validation and leakage checks
Human ratings and a leakage audit test the quality of an automatically curated dataset.
Captions track the captured action
4.16/ 5 action match
81% of ratings are at least 4/5. Hand-specific caption faithfulness averages 3.79/5 across 370 ratings.
Recovered hand motion is generally usable
3.53/ 5 reconstruction quality
Raters assess jitter, discontinuities, and unnatural finger poses while viewing reconstruction beside source video.
Source overlap does not drive the ranking
≤ 2.6 ptsabsolute R@1 shift
Removing test clips whose source video appears in train preserves the ranking of all four evaluated generators.
Human evaluation
Caption fidelity by detail level
Fine-grained caption accuracy remains stable across levels. Hover for mean scores and the share of ratings at least 4/5.
Dataset diagnostics
Motion statistics explorer
RoMo Hands reduces static clips to 0.2%. Switch views to inspect hand engagement, bilateral symmetry, and temporal quality.
Citation
RoMo Hands
@inproceedings{BenShabat2026RoMoHands,
  author    = {Ben-Shabat, Yizhak and Zhang, Jiahao and Liu, Joseph and Moon, Seonghyeon and Lee, Young-Yoon and Jiang, Haomiao and Jacob, Oren and Kapadia, Mubbasir},
  title     = {{RoMo Hands}: A Large Scale Richly Organized Text to Hand Motion Dataset},
  booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
  year      = {2026},
}